the problem
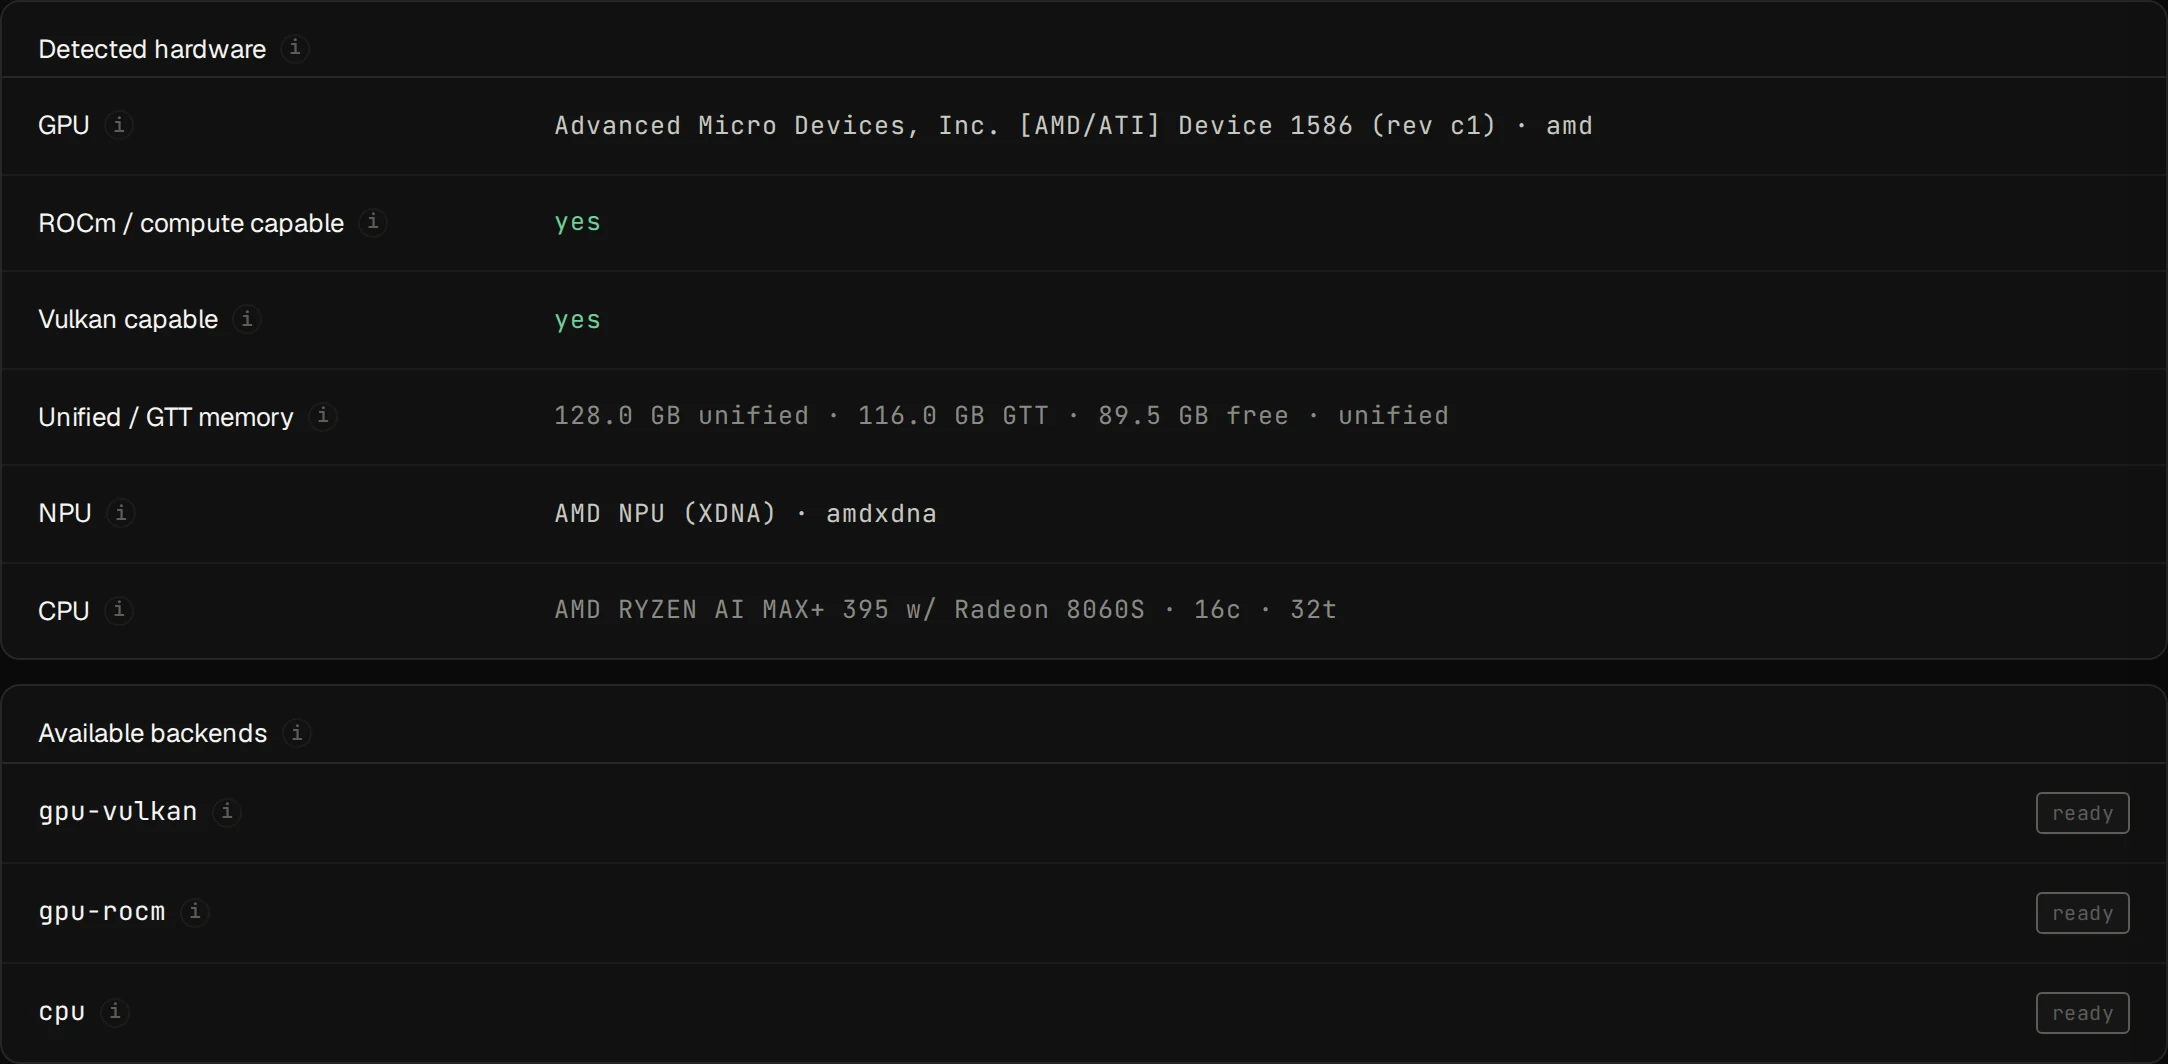
Strix Halo machines have the memory to run large models locally, but the software path was a pile of scripts. We wanted a platform you could install, point at a model and trust in production.
what we built
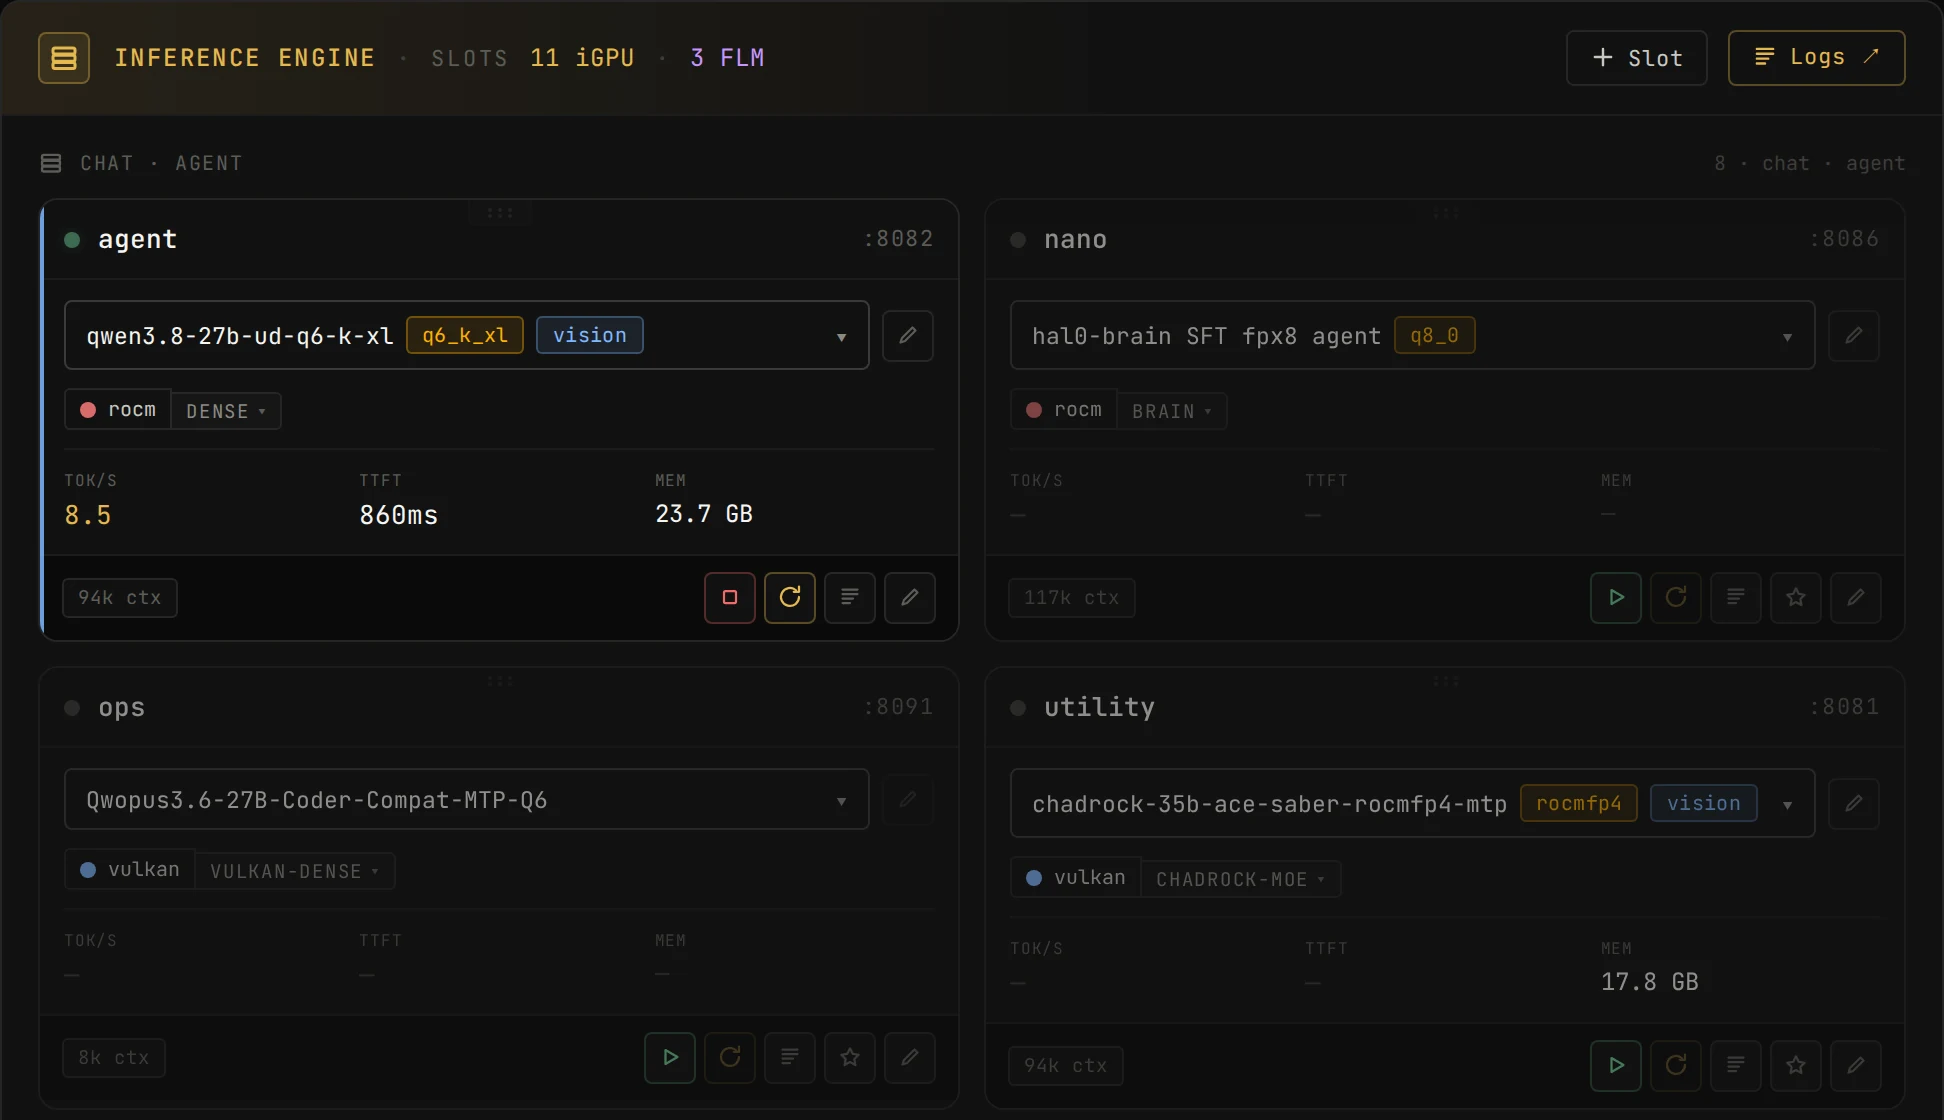
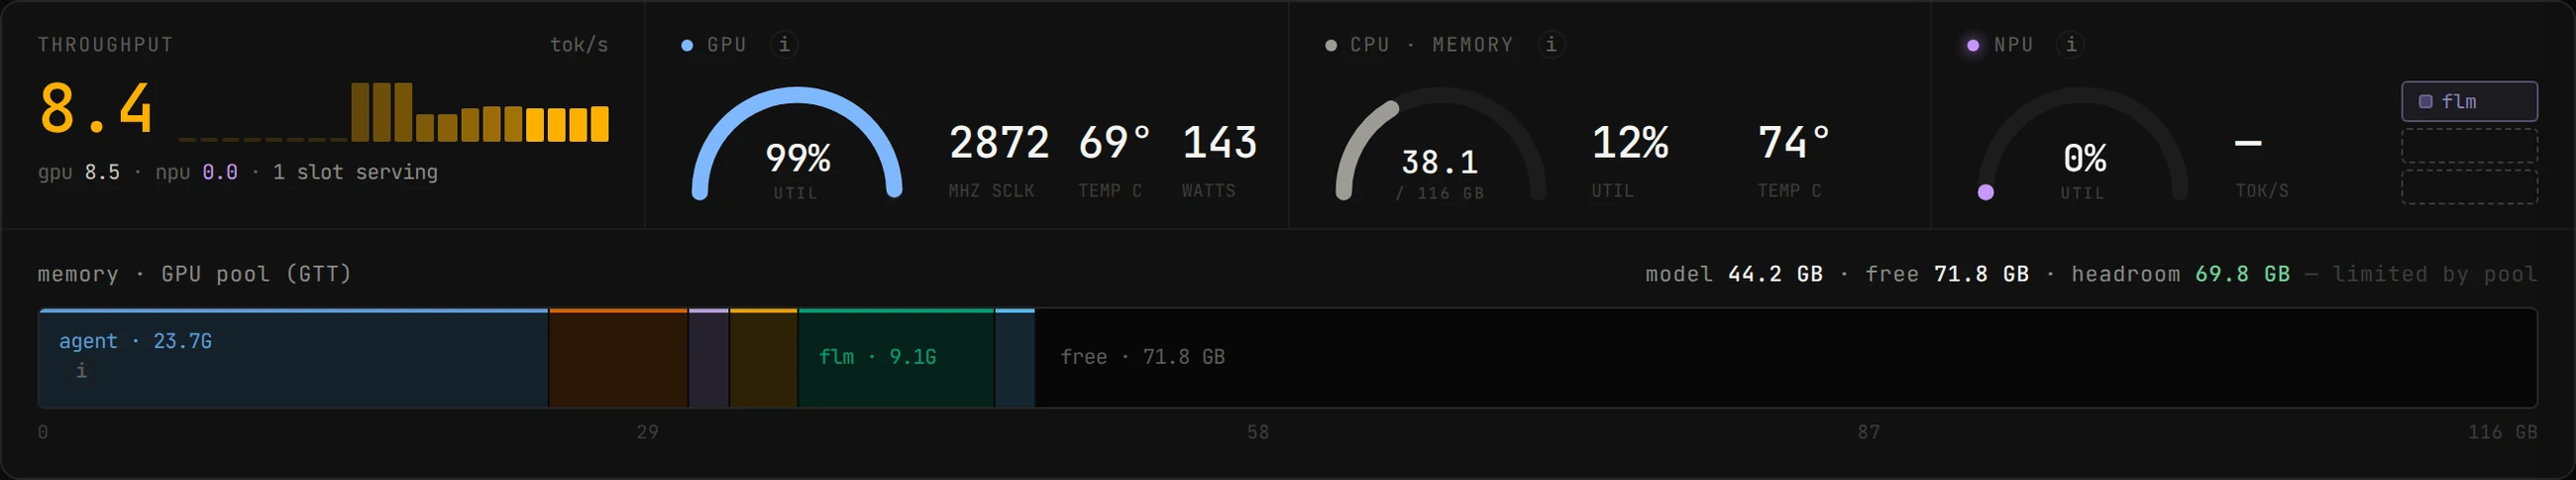
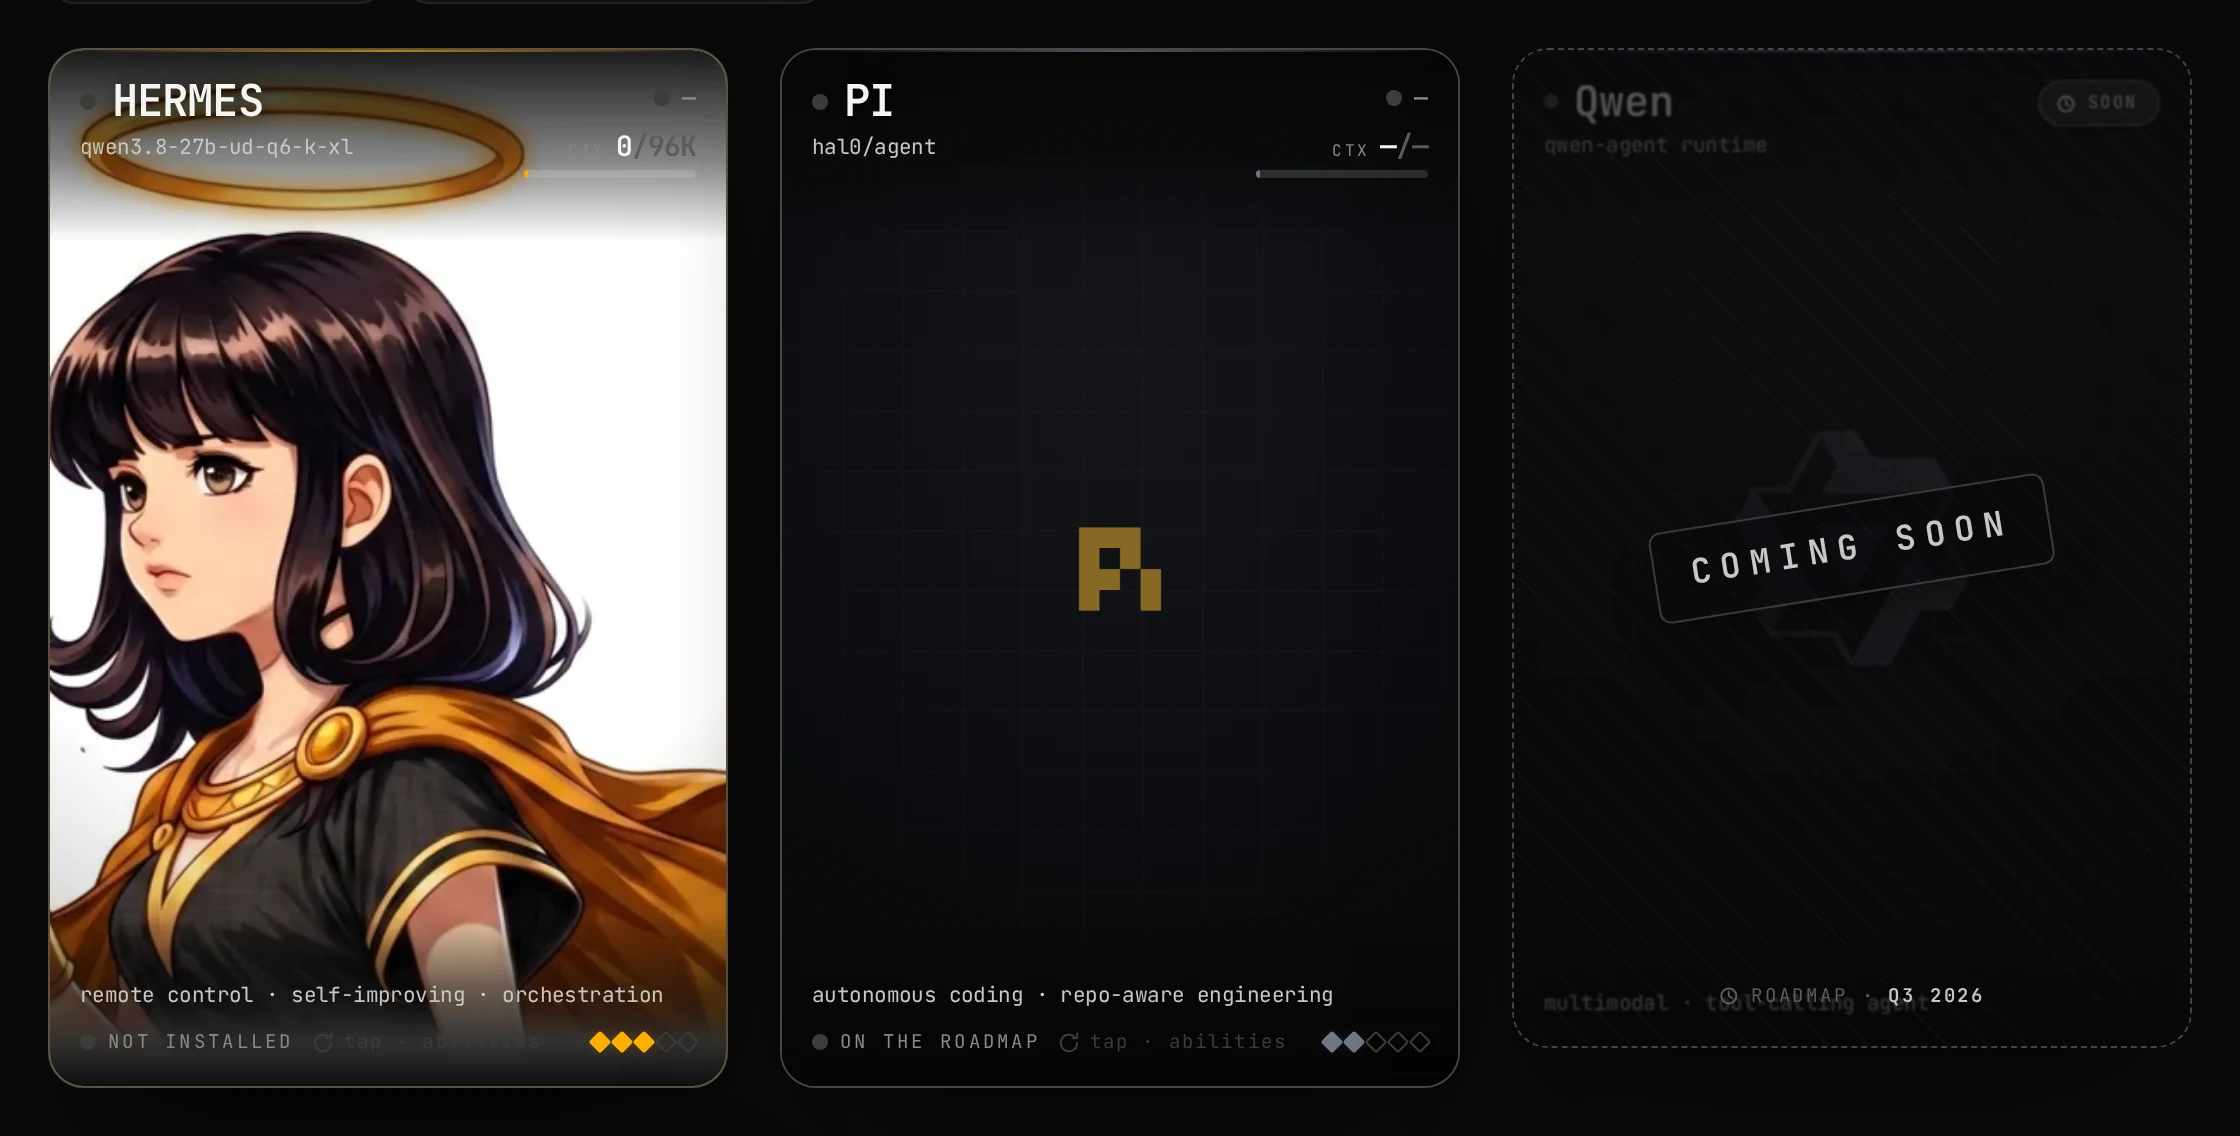
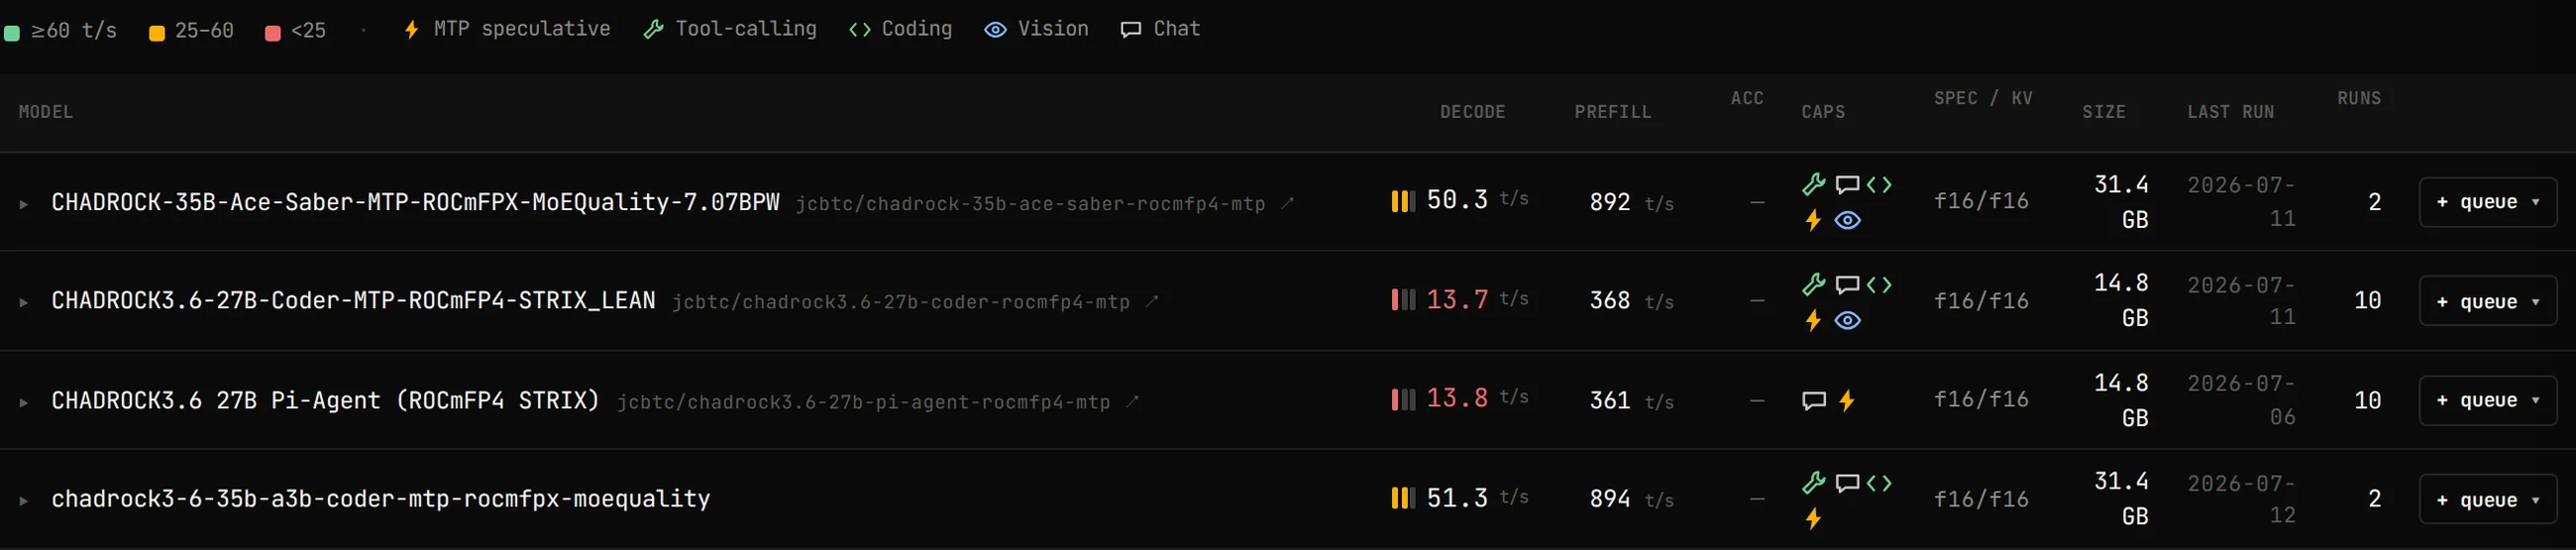
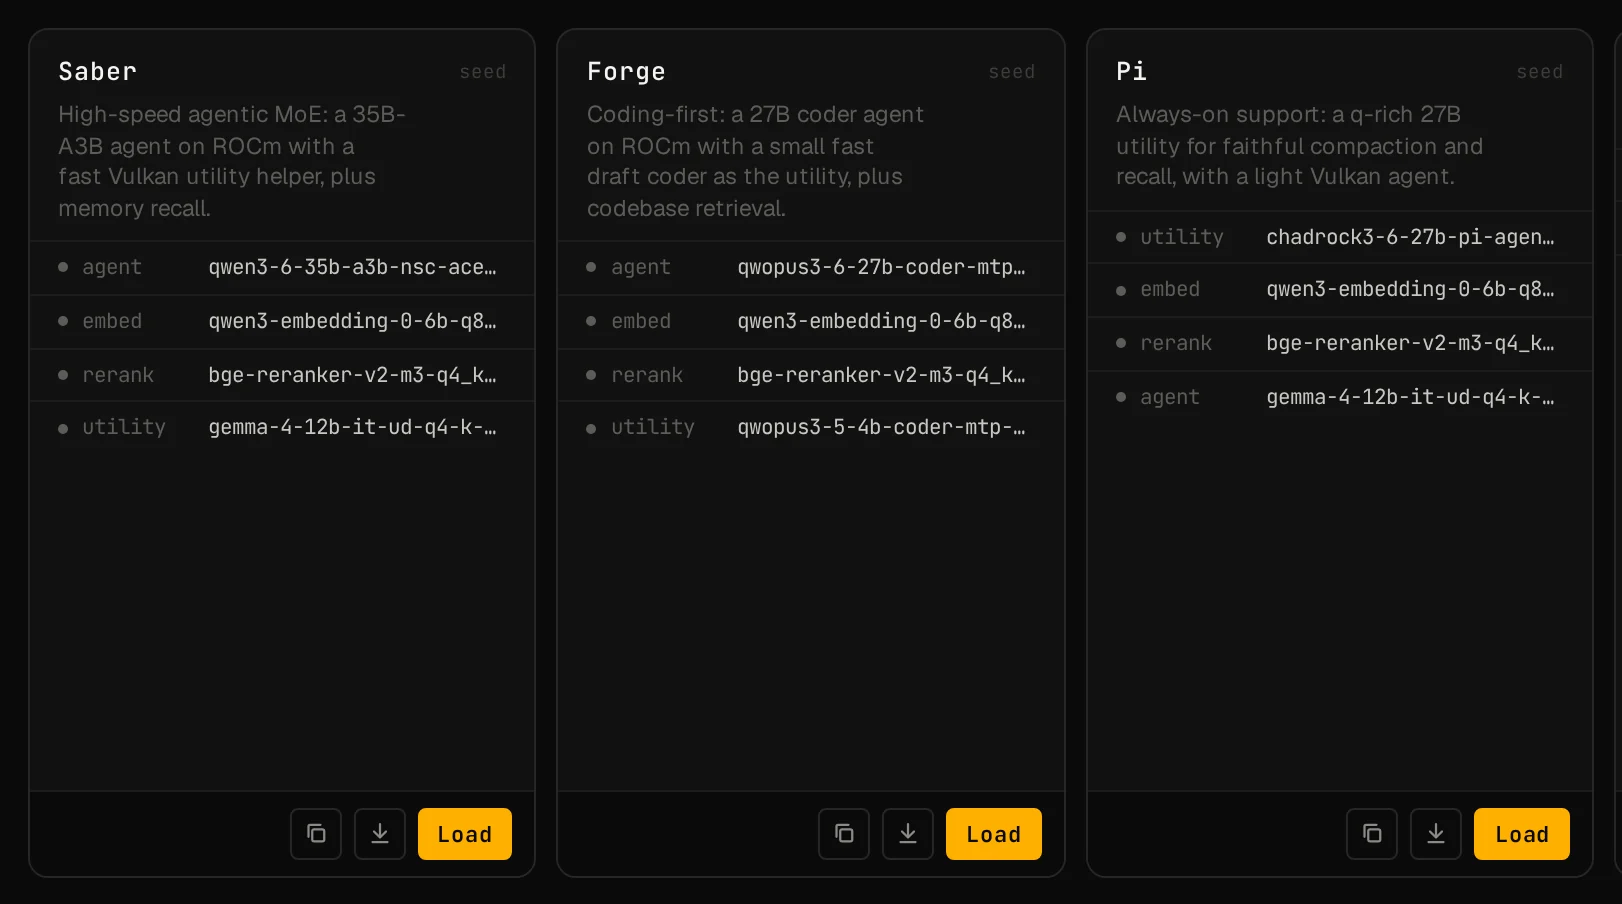
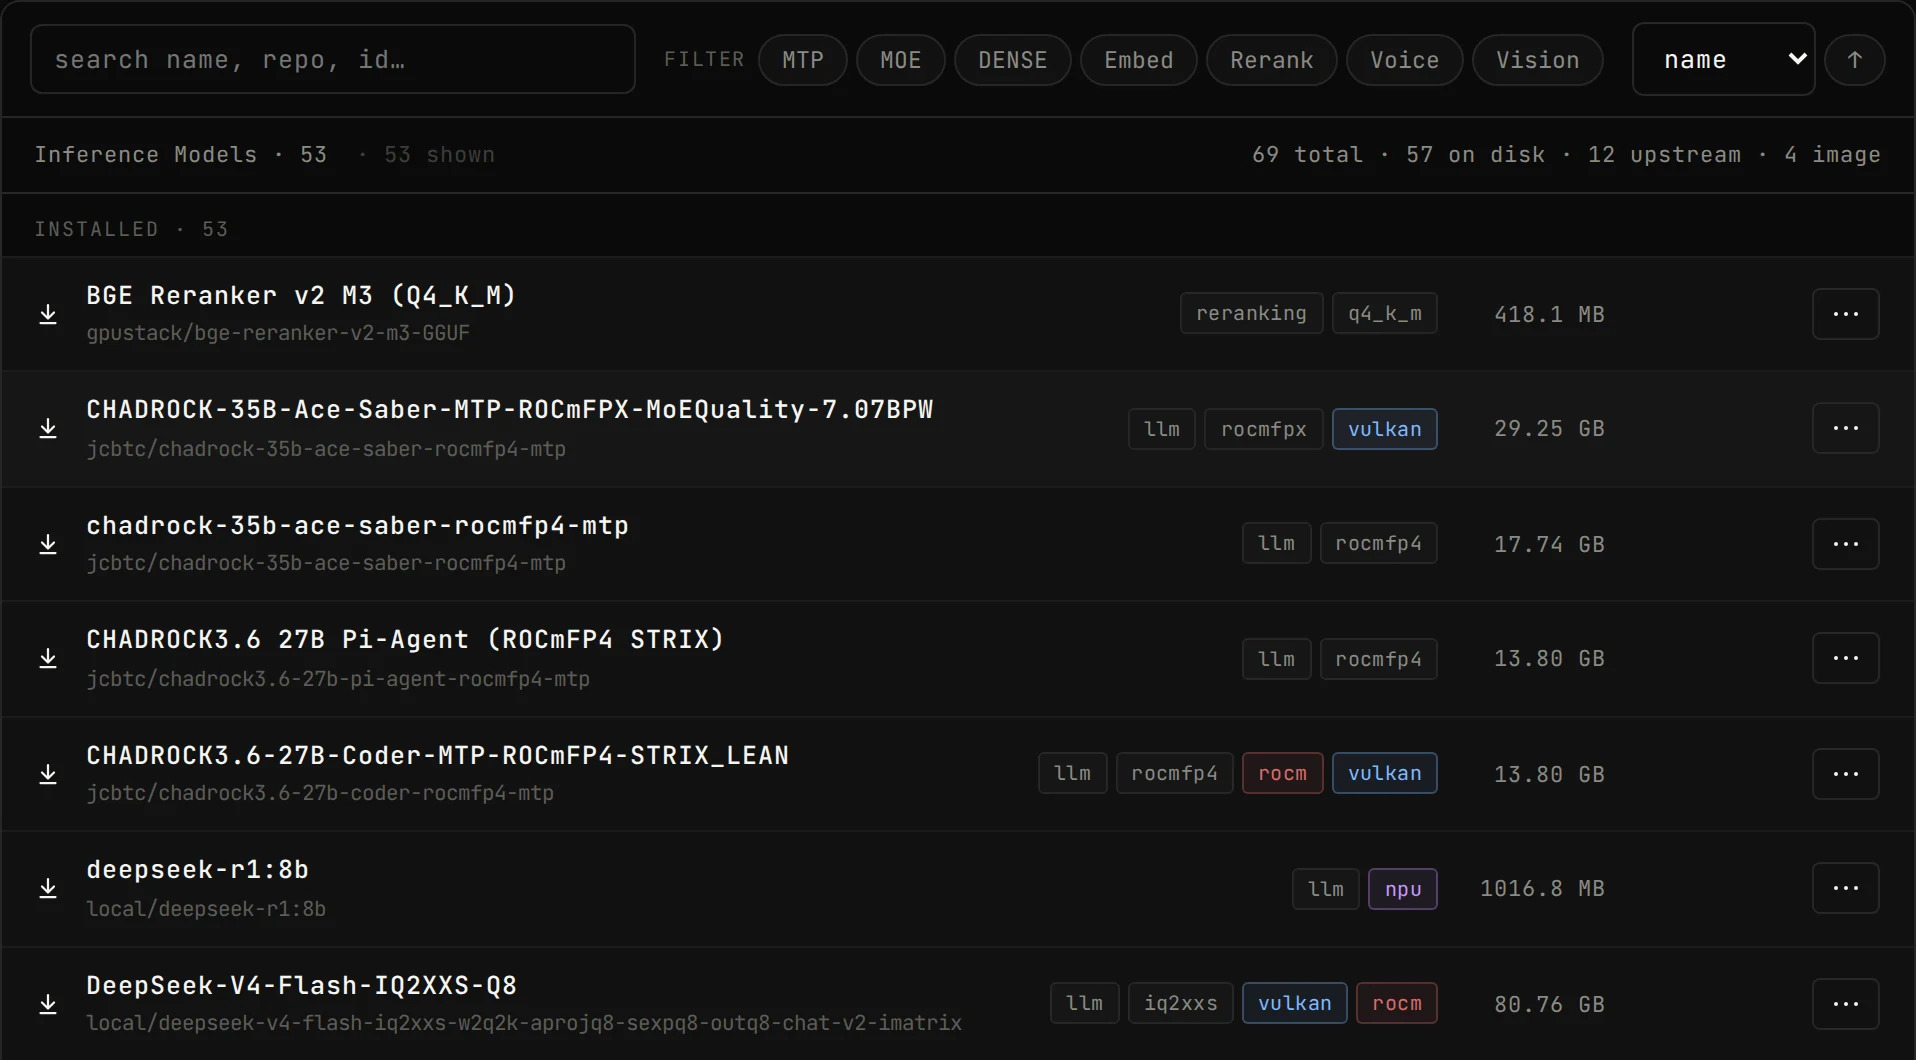
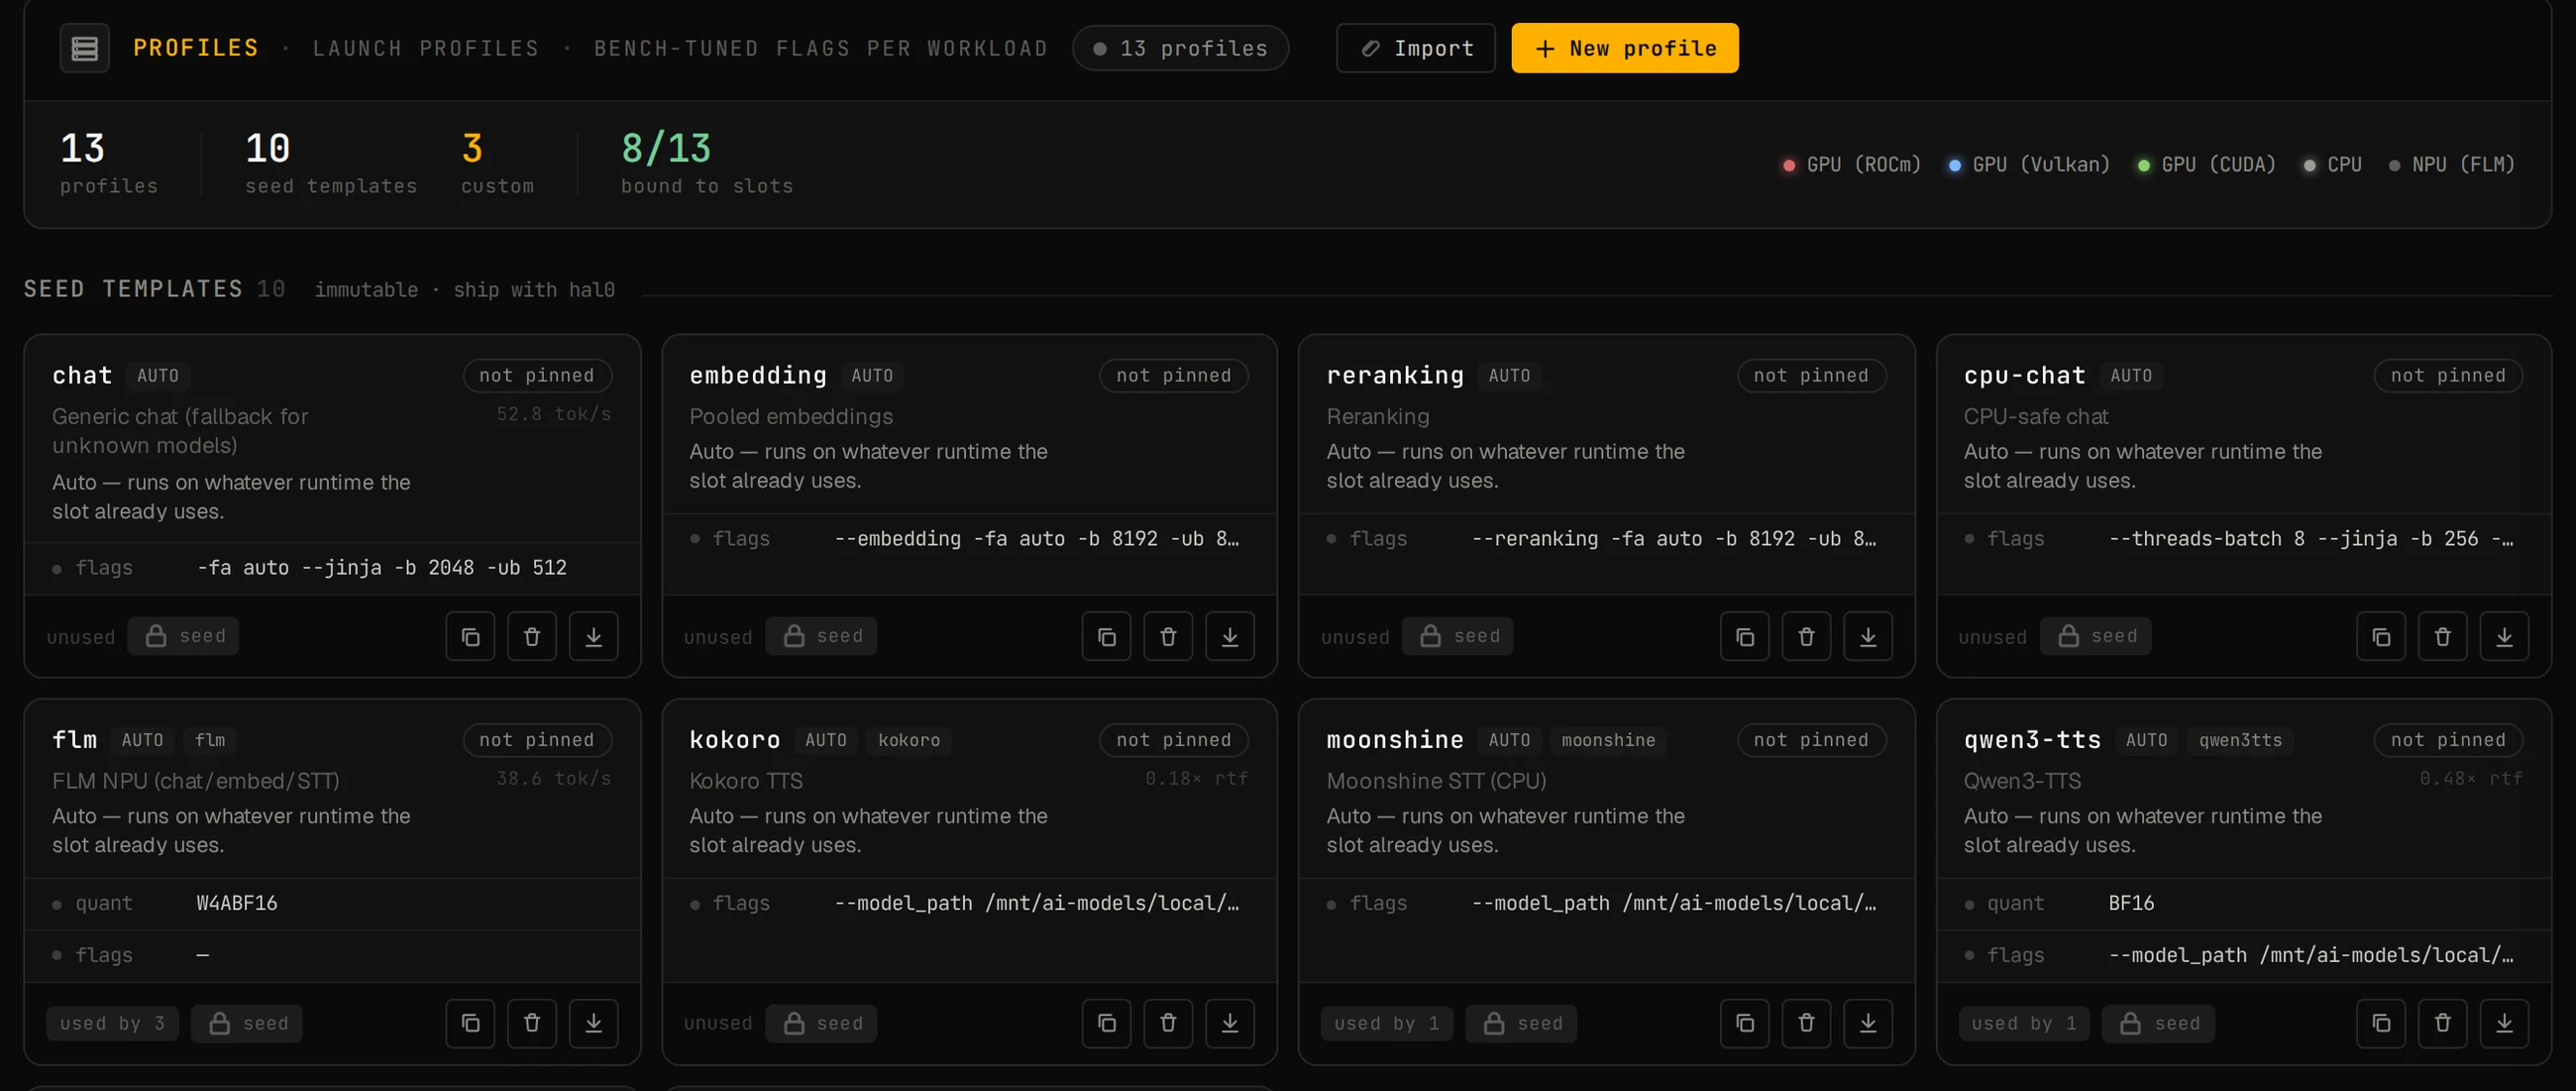
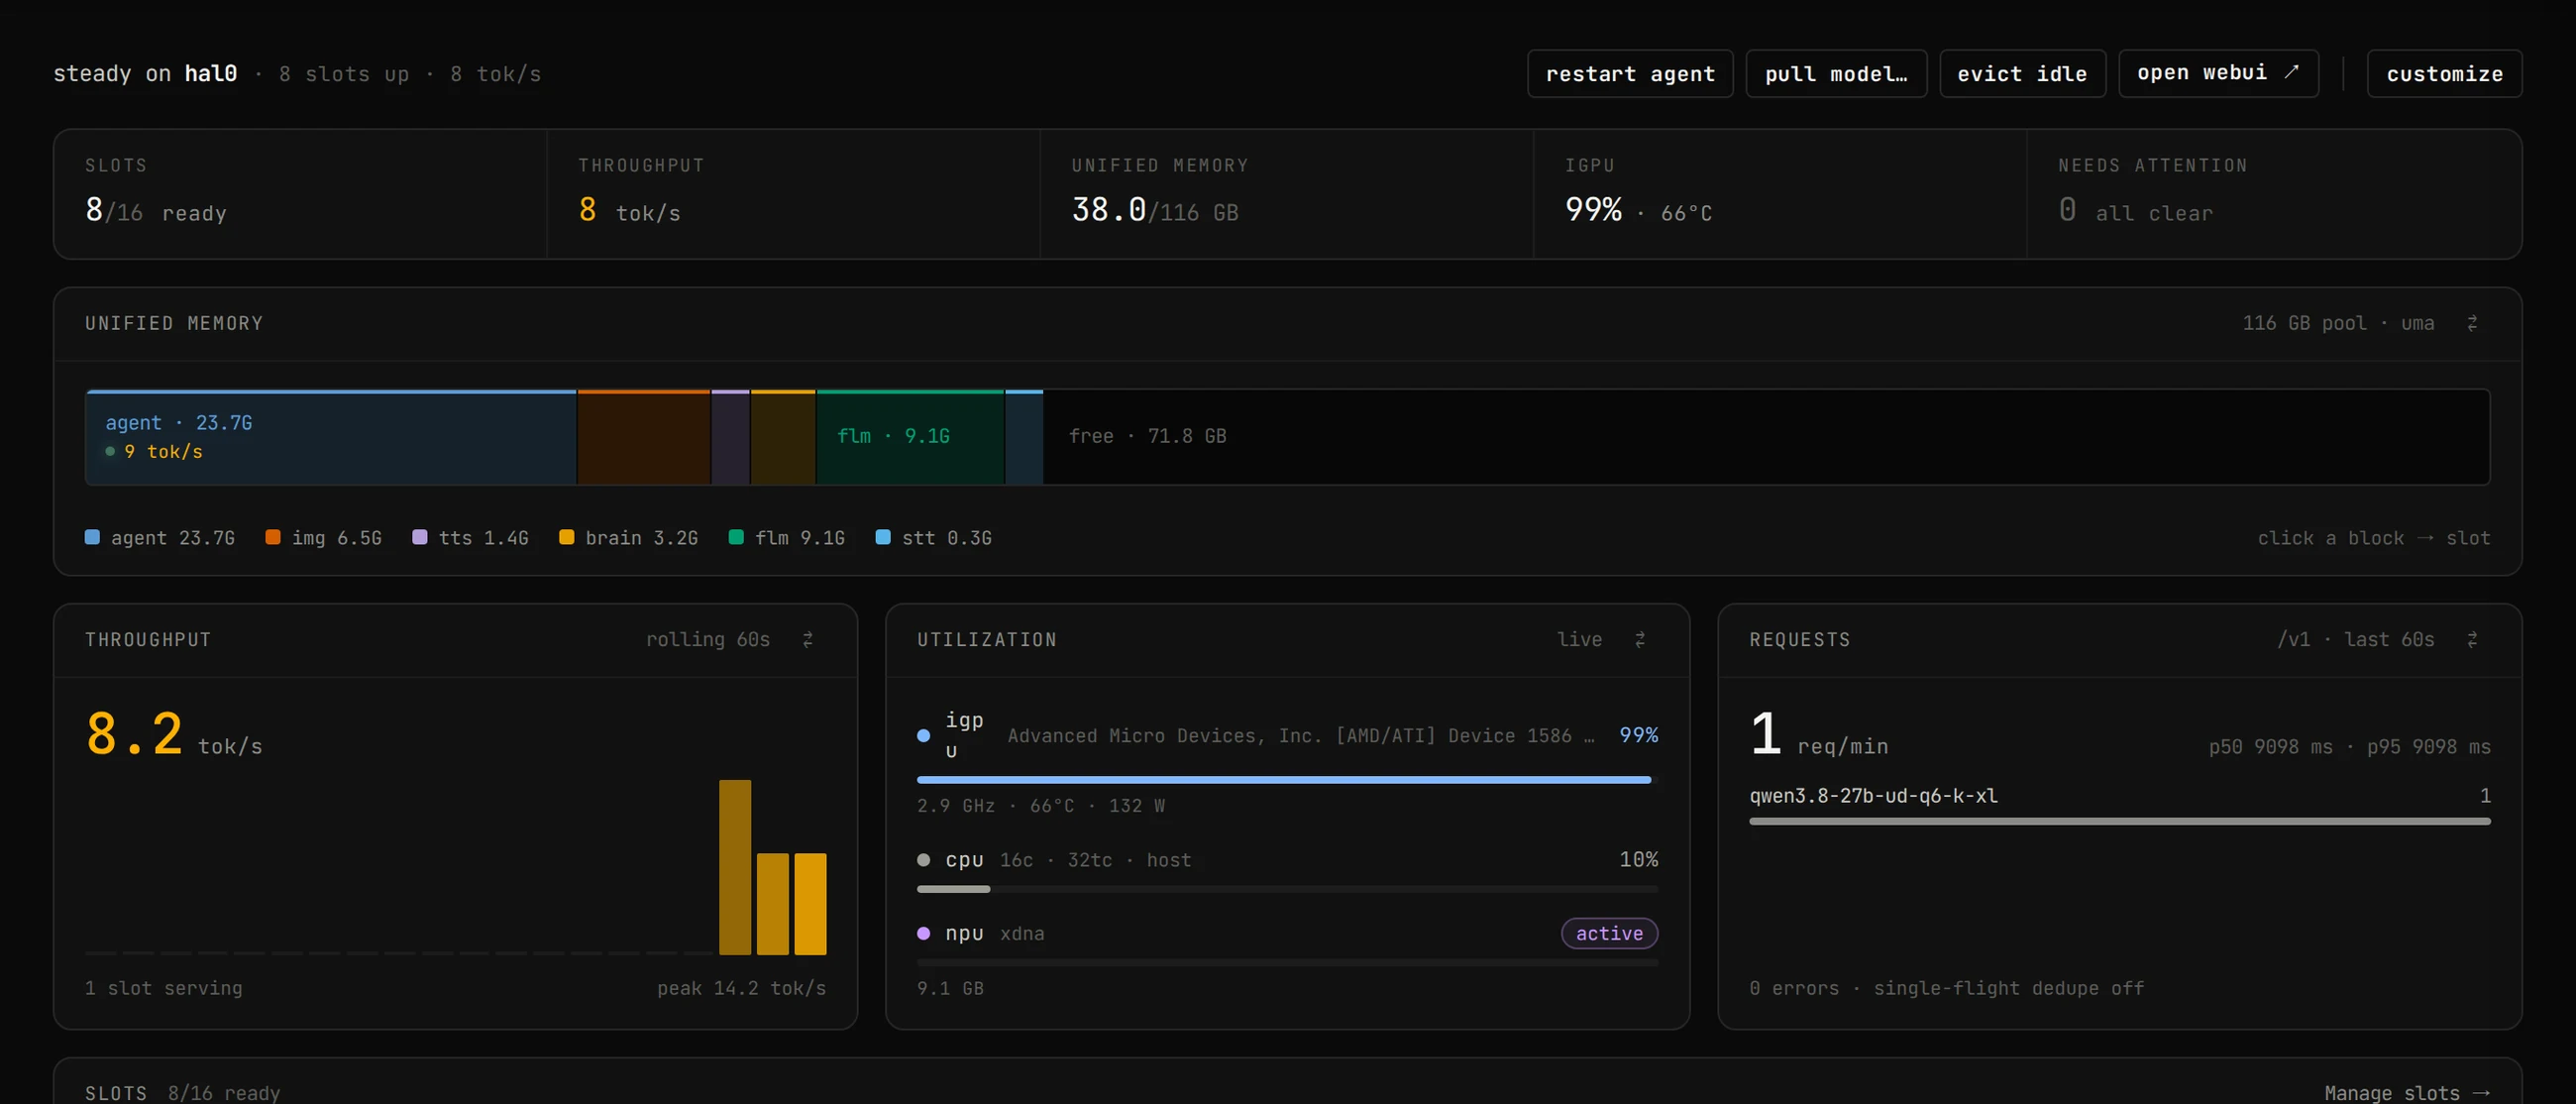
An open-source inference server and control plane: model management, an OpenAI-compatible API, hardware-aware scheduling and a plain web console. Packaged for a single box or a small cluster.
what we'd do differently
Ship the console earlier. The API was solid for months before anyone could see what it was doing.